Category Archives: SQLServerPedia Syndication

This category is for SQLServerPedia Syndication

PGH.NET Code Camp Review

This past weekend I had the pleasure of helping out David Hoerster (bio, twitter) with the setup of PGH.NET Code Camp.  Why, would I want to get up before the crack of dawn to help?  Well for starters David is a die hard Pittsburgh Pirates fan like myself.  Okay the real answer, is that I wanted to help with the code camp before I ran my first SQLSaturday in West Virginia.   This was a great practice before the game starts on May 1st.

In short I learned that if you have good volunteers it’s actually not too hard to have a great event.  If the event is free there will be people who just don’t show.  I guess mowing their lawn is more important than free training?  People will also leave before the event is over.  I could be wrong but I thought about half of the crowd left before the last session ended.  Finally, if a speaker doesn’t show you could replace the session with speakers panel.  This was a great move and actually was my favorite session of the day. 

SQL Server 2008 for Developers

During the day I also did a presentation on SQL Server 2008 for Developers.  I presented right after lunch and expected the majority of the crowed to have a food coma from the free burritos but this was not the case.  It actually was a nice interactive session. The following are a few quick facts from the presentation. 

About 40 people attended this session and only five of them are currently using SQL 2008.  I know this is a small sample size but it makes me believe that there are a lot of people out there still on SQL 2005 or SQL 2000.

The majority of the people awake (yes,  a few experience the food coma) were really impressed with using the real-time debugger to debug stored procedures, using merge to replace truncate table insert into table and use TVP to pass a data table in as an input parameter.

Follow-up Answers

The following are answers to some questions that were asked after the session.  Thought I would answer them here so others could find them in the future.

Can I create an index to filter based on dates?

Yes, you can.  I believe this is a new feature added in SQL Server 2008.  The following script will execute.

CREATE NONCLUSTERED INDEX FIBillOfMaterialsByStartDate
    ON Production.BillOfMaterials (ComponentID, StartDate, EndDate)
WHERE StartDate > '20000801' AND StartDate < '20010801';
GO

Checkout this MSDN link for more on Filtering Indexes. 

How can I make my database run faster? 

This is always a fun question and a hard one to answer without looking at the database and the server it resides on.   I recommended that this individual start with the free performance boosts.  This is also known as managing your indexes.   To do this checkout the following great links with video from SQLServerPedia.

Can I find the last time database objects were modified?

Yes, check out this link for a script that does the following task

Book Review: “Confessions of a Public Speaker”

This year I made a goal to read six new books and to share my experience with everyone via book reviews.  This is the first review of the year and I am excited to give feedback on a book I really enjoyed.  Normally self help books put me to sleep but this was an exception as it was informative and entertaining to read.  If you plan to do public speaking in the near future I highly recommend this book.

My motivation for reading “Confessions of a Public Speaker” by Scott Berkun is simple.  I find myself doing more presentations and I want to improve my craft.  This year I will be speaking at PGH.NET Code Camp in April and also at SQL Saturday #36 in Wheeling, WV. Public speaking is not easy for me.  I completely agree with Adam Machanic’s blog post.  It takes a lot of practice and some reading to see how others succeed. Therefore, I want to take any advantage I can to make my presentations better.   The lessons I learned in the first chapter alone made this book worth the $17 on Amazon.

The following are some very important lessons learned.  Most people at your presentation hope you do well but also hope your presentation ends soon.  It’s funny, after I read this I started laughing because it’s so true. I also learned to know your material but know you shouldn’t be perfect.  Normally, I try to be a perfectionist so this is something I had to know.  I cannot go back in time and correct my mistakes. Ummm… maybe I can I will have to add this to my todo list.   Finally, I learned it’s the mistakes you make before you present that matter the most.  I will dive into this with my confession below.

Being that the title of the book is “Confessions of a Public Speaker” it’s only fair to include a confession of my own.  With experience I learned that I must take control of what I can control.    Three years ago I did my first presentation at the Pittsburgh Code Camp and did a presentation on extending the Reporting Service API’s.  While no one booed or threw fruit at me the presentation was a hot mess.  I was modifying slides in the speakers room, I didn’t do a practice run of the demos, heck I didn’t go through the audience’s point of view when I built the presentation.  If I would have taken care of what I could control (my presentation) this could have been a killer presentation.  Regardless, it was a great learning opportunity which made my future presentations much better.

If you want to improve your public speaking I highly recommend Confessions of a Public Speaker. This book will stay on my bookshelf within an arms reach for quite some time.

Cutover 30+ GB databases in 60 seconds with SQL Server 2005/2008

You kid brother just messed up a database migration.  You now have sixty seconds to migrate a 30 GB database or you kid brother is…
Okay I gave it a shot 🙂

If you are familiar with moving databases across servers most likely you are using one of the following methods.  Today I am going to write about what goes on during these methods with a focus on speed and provide another option that might work for you.

  • Detach/Attach
  • Copy Database Wizard
  • Backup/Restore
  • 3rd Party Tools

Detach/Attach

The detach/attach method allows you to detach and reattach databases. Therefore, in order to move a database from one server to another you have to detach the database, physically move the data and log files to the new server and then attach the database.  An unforeseen bottleneck with this strategy might be network latency. While this method is very straight forward and simple how long can the database be offline while you are moving the database files (mdf, ndf, ldf) during the detach/attach process?

Copy Database Wizard

The copy database wizard is a tool that leverages SQL Server Integration Services (SSIS) to copy a database from one server to another.  The account that the package uses at runtime has to have sysadmin role on both the source and destination instances.  You have two options during the copy process.  The first method is detach/attach see the paragraph above for feedback on using detach/attach.  The second method includes using SMO to script database objects.  This method keeps the source database online during the copy but is much slower than the detach/attach.  Therefore, I have no feedback on this method.  Have you used it? If so please add your comments.

Backup/Restore

Assuming you are using the Full recovery mode for your database the backup restore method for moving a database involves taking a full backup and a transactional log backup where you backup the tail of the log, and leave the database in restoring state.  This will take the source database offline keep the data in sync.  With restore time being a factor you could restore the full backup and do incremental transaction logs up to the point of cutting over assuming assuming no full backups occurred on your database while you started applying transactional backups.

And the winner is…

Drum roll please……..  And the winner is Database Mirroring in High Availability Mode as it can allow you to cutover failover to migrate huge databases in less than sixty seconds.  Okay I might be cheating, it will take much more than sixty seconds to configure. The important fact is that it will seam like it only took seconds to the end users. If your application uses .NET 2.0+ framework and you configure client side redirect the end users might not experience an outage at all.

To setup database mirroring it is highly recommended to make sure the principal and mirror database engine services are using service accounts, they also need access the the ports used by SQL endpoints, and more….  Check out the MSDN site for a great guide for Database Mirroring

Its on like Donkey Kong!

I am glad to announce that SQLSaturday is coming to Wheeling, WV.  This will actually be the first SQLSaturday in West Virginia. The goal is simple, provide a free day of training on  Saturday, May 1st 2010 for SQL Server DBA’s and developers.  This event focuses on speakers, providing a good variety of topics, and making it all happen through the efforts of volunteers.

SQLSaturday

Below is the following list of submitted topics as of February 3rd.  If you would like to speak the call for speakers is still open until March 15th. We are firm believers in SQLSaturday’s goal to find, grow, and feature speakers that include the next generation of talent.  If you are an MVP or first time presenter we will try to fit you in.

SQLSat36Image

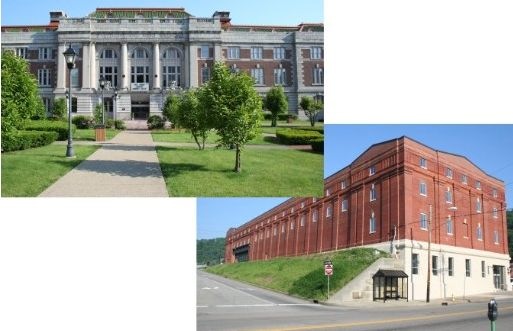
Registration is now open so you can sign-up to attend SQLSaturday #36.  This event will include a free lunch, door prizes and a post training party.  Did we mention that its free?  Below is photo of West Virginia Northern Community College the venue for our event.

wvncc

We look forward to seeing you in May.  In the meantime you can follow our SQLSaturday blog posts here.

Goals for 2010!

Yes, I know it is already 2010.  I am a little behind but still wanted to officially write down some goals for the new year.   Actually I should get partial credit as I started on the whiteboard in December.  Anyways, this will help hold me accountable for my goals, give me something to review quarterly through the year and also keep my friends on the internet aware of what I am trying to accomplish this year.

goals

  • Be a better Husband

    I have to admit there has been several times in my life where I put work, groups and other things ahead of family time.  My most important goal for the year is to change this.  I plan to have at least one night per week where I put the computer down and spend time with the family.  I also plan to make this the year I take Nina to Spain.  Yes, those who know me well know I didn’t complete Spanish a couple times in high school.  Hopefully, we will be able to learn the language of the land together in the next few months.

  • Make an impact to improve my community

    I am a young (28 year old)  Database Administrator, Programmer, Information Technology Professional who lives in Wheeling, WV (50 miles down this Ohio River from Pittsburgh, PA). This year I will serve my local community by becoming the President of the Greater Wheeling Chapter of the Association of  Information Technology Professionals and the Region 18 Vice President.  Our biggest initiative of the year will be implementing the first SQLSaturday in West Virginia.  We will provide free conference event that will bring Information Technology professionals to Wheeling to obtain free training on SQL Server,  .NET and professional development.  I am also highly involved with OVConnect the Ohio Valley’s Young Professionals group.  Through this group we will provided several events that connect young minded people together.

  • Continue to improve my communication skills

    I admit it I am guilty as charged.  While I read several blogs and technical books I don’t dive into non-technical books often.  This year I plan to read six non-technical books during the year and write reviews of them on this blog.

    Speaking of blogging if you are following this blog you know my blogging last year was not consistent.  Therefore, I am going to try to make sure I have at least one new post every two weeks.  I will also try to blog about different things going on locally, personally and with technology.

    Finally, I also plan to do more technical presentations this year.  I hope to do four presentations.  You will be able to catch me presenting at Pittsburgh .NET Code Camp and SQLSaturday in Wheeling.

  • Continue the certification path for MCITP SQL Server 2005

    In 2009 I completed the 70-431 exam which makes me a Microsoft Certified Technology Specialist on SQL Server 2005.  This year I plan to take the next step and become a Microsoft Certified Technology Professional in SQL Server 2005.  You might be  wondering why would I or you want to do this?  There are a few reasons I will share.  First, a great friend of mine once told me its a great way to polish your skills.  Second, I believe that the certification process forces you to learn topics you wouldn’t learn unless you complete the process.  Third, the objectives of the exams line up with some project goals at work so I can kill two birds with one stone.

  • Improve my networking and social networking

  • In 2009 I  dove into social networking via blogging, twitter (johnsterrett) LinkedIn, and Facebook.  While I have lots of great connections through these networking portals its hard to keep track.  Therefore, I have a simple networking goal for 2010.  I want to build lasting relationships with 7 to 10 new individuals.

    Attend PASS 2010 Member Summit

    This goal is actually very straight forward.  In fact, I am actually cheating.  I just signed up for the conference and look forward to meeting other DBA’s and SQL Developers at this event.  If you work with SQL Server I highly recommend you do the same.

Use UGSS and GITCA to support your User Groups

If you are supporting/running a user group or  interested in becoming a technical presenter this blog post will help you. I am starting to help with the Pittsburgh SQL Server User Group and I wanted to share some knowledge learned from working with the Greater Wheeling Chapter of the Association for Information Technology Professionals. If your user group is based on technology (AITP, INETA, PASS) etc. I highly recommend you look into leveraging the resources provided by UGSS and Culminis GITCA.

Today I received an email reminder to sign up for the Q2 UGSS User Group Kit and this motivated me to write this blog post for leaders and presenters who are not familiar with UGSS or GITCA.  At the end of the day you need to offer something of value (knowledge, training, networking, swag)  for people to attend your events. I want to commend both UGSS and GITCA as they provide support to increase the value of your user group meetings.

Global IT Community Association (GITCA)

For starters Culminis is now GITCA.  Global IT Community Association (GITCA) represents over 700 member organizations and over 3.7 million IT professionals.   GITCA is the world’s largest international not-for-profit independent organization powered by dedicated volunteers devoted to the development and growth of the IT community by providing services to support leaders and connect user groups, associations, and student IT organizations.

The following is a list of benefits for user groups:

  • SharePoint hosting for user group
  • LiveMeeting account online meetings
  • Event Support
  • Community Development
  • Access to User Group Support Services (UGSS)  more on this below.

To apply check out the requirements and sign up if you qualify.

User Group Support Services (UGSS)

User Group Support Services (UGSS) is dedicated and committed to serving technical community members and leaders worldwide.  UGSS provides resources that will ignite your efforts as leaders and invigorate your experience as members.

The following is a list of benefits for Community Leaders:

  • Get speakers for your events – if you are interested in presenting sign up here. Groups will find you and ask you to present.
  • Get funding for your events – yes, they will help sponsor your events.
  • Get publicity for your events
  • Get more publicity for your events
  • Get swag (content, demos, samples and more) –  the photo below shows some items I received during the last kit.

16348_754336456627_9635606_42370080_7481877_s

If you are the leader of a user group, a presenter, or someone who would like to sponsor events apply here. If you have any questions feel free to shoot me an email at jsterrett at gmail dot com and I will do my best to point you in the right direction.

Disk usage monitoring with Data Collector

Today, I am jumping into Adam Machanic T-SQL Tuesday challenge with the following post.

Recently, I created a build request to have a new server to move SQL Server databases.  I put together an estimate for the space needed for data, logs and backups and included this information in the build document.  This request was put in the queue and all was well.  Once this request popped to the top of the queue I reviewed the size of database files using Idera’s Space Analyzer and noticed unexpected data growth in a few of the data files.  Thankfully, the data collector and Management Data Warehouse (MDW) was enabled which helped us track the unexpected data growth.

Introduction

SQL Server 2008 introduces the data collector and the management data warehouse (MDW) into SQL Server Management Studio (SSMS). The Management Data Warehouse exists by leveraging the data collector and a MDW database and custom reports. This allows administrators and developers the opportunity to do some proactive monitoring. If you are familiar with the Performance Dashboard then you will be impressed with the new Management Data Warehouse.

How does the data collector help you?

Out of the box, the data collector provides you with the tools to monitor disk usage, server activity and query statistics.  Therefore, when you are asked the following questions.  How much space do we need for database xyz? Why did database xyz grow from size 123 to size 456? you can use the data collector report to help answer these questions.  For example, below is a screen shot of some sample databases.

image

You can see that the third, forth and fifth databases had their current size changed.  I want to focus on this fact because it doesn’t represent the data inside the database files.  This means the actual data files (mdf, ndf, ldf) are growing which can cause disk fragmentation. You want to avoid this when possible.  Ideally, you want your database graph to be a straight line like the sixth database.  Next we will click on the graph for the fourth database and drill deeper to the analysis.

image

image

Looking at the two image above you can see that the data size multiplied during a six hour between noon and 6pm on November 30th.  We were then able to use this information to determine the cause for the unexpected growth of data.

Conclusion

I think this is a great tool to troubleshoot unexpected data growth.  I look forward to using this tool as part of the process to estimate future database growth.

Pittsburgh SQL User Group: Data Warehousing Presentation

Today, I am giving my first presentation at my local SQL Server User Group.  Below are links to the slides.  I will also add some more resource here after todays presentation.

Introduction to Data Warehousing slides

DEMO: Build Your First Cube

Below is the description of the discussion.

November’s presentation will include an Introduction to Data Warehousing with SQL Server presented by John Sterrett, a Database Administrator and Web Engineering Specialist for Orrick, Herrington & Sutcliffe LLP.  If you are interested in learning how Analysis Services, Integration Services and Reporting Services can provide Business Intelligence this meeting is for you.  We will start with the basic concepts of data warehousing including key terms and definitions.  Next, we will cover some sample business cases while we walk through the process of designing a data warehouse.  Once this session is complete you will be able to develop your first cube.

Date: Monday, November 16, 2009

Time: 11:45 a.m. Registration; 12:00 PM – 2:00 p.m.

Venue: Council Training Room, 2000 Technology Drive, Pittsburgh, PA 15219

Cost: No charge

RSVP: Email Heather Jones at Heather_Jones@Dell.com

If you have any questions, need more information, or would be willing to participate in any upcoming presentations or discussions, please Heather Jones at Heather_Jones@Dell.com.

Data Warehouse: Facts and Measures

A few days ago I wrote a post that gave an introduction to dimensions.  Today, we are going to continue covering the basic concepts included in dimensional modeling by covering an introduction to fact tables and measures.  These posts are all part of the introduction to building a data warehouse with sql server series.

What is a Fact Table?

A fact table is a table that joins dimension tables with measures.  For example, Lets say you wanted to know the time worked by employees, by location, by project and by task.  If you had a dimension for employees, location, project and task you would create a composite primary key using these foreign keys and add an additional column for the time worked measure. (more on measures in a little bit)

Keep in mind that fact tables are huge unlike dimension tables.  Fact tables are usually built to contain a hundred thousand records on the low side up to billions of records on the high side.  Therefore, these tables must be normalized to be efficient.

A fact table is normalized when it consists of the following two things:

    1. A composite primary key using the foreign keys to the dimension tables.
    2. Measure(s) used for numerical analysis.

What is a measure?

A measure is normally an additive numerical value that represents a business metric.  You are also not limited to a single measure.  You can have multiple measures within a fact table.  For example, if your fact table is used to track purchases internationally you might have measures for each type of currency.  If you are building a fact table for the retail industry you might also have the following measures cost, list price, average sale price.

Next, you can take a look at my demo on building your first cube.

Introduction to Dimensions

Today, we are going to quickly cover one of the basic concepts included in dimensional modeling.  We are going over the basics of dimensions, attributes and hierarchies.  We will review how they are related and how they work within Data Warehouses.  If you are looking for an introduction to building a data warehouse click here.

What is a Dimension Table?

A dimension table provides the description behind the analytic numbers.  It describes the who, what, when, where and why behind the facts. Dimensions are normally broken down into groups (tables) and they contain several attributes (columns).   Unlike a fact table the dimension table is not normalized.  Generally, dimension tables have many columns but a limited amount of rows. Dimension tables normally provide two purposes in a data warehouse, it can be used to filter queries and to select data.

Several data warehouses include the following dimension tables products, employees, customers, time, and location.  Lets say your business requirement is to provide an  time tracking data warehouse.  You would to want to implement a employee dimension table that included at least the following attributes (columns) first name, last name, status, start date, hire date, end date, department name title, salary etc….   we could actually go on and on and this is okay as long as the attributes support your business requirements.

image image

What are dimension hierarchies?

Dimension hierarchies provide a way to define a relationship between multiple attributes within a dimension. They are commonly defined as a structure to provide drill up and drill down capabilities.  You can have multiple hierarchies within a dimension. For example, in a time dimension you might want to have two separate hierarchies, one for fiscal year and another for calendar year.  These two dimension could contain the following attributes year, quarter, month, day.

image

Best Practices for designing a Dimension table

  • Use a unique identifier integer column that is auto incremental as your primary key.  This is commonly known as a surrogate key.
  • Use the source’s primary key as an alternating key.
  • Any additional attributes (columns) that describe the business entity

Slowly Changing Dimensions

Now that we know how to build a dimension we need to consider how the data is stored.  Yes, occasionally the attribute data changes.  For example, lets pretend you are a die hard Pirates fan and built a Data Warehouse to do analysis on your favorite players.  How would you handle promotions like Andrew McCutchen getting called up from AAA Indianapolis to the Pirates?

The following are options to handle slowly changing dimensions:

  1. Do nothing (type 0).  This approach is highly not recommended.  This cannot guarantee history preservation and includes the least control over managing changed attributes.
  2. Overwrite old data with new data (type 1)
    This completely overwrites the previous attribute value.  This could be ideal if you had a spelling error or the historical value of this column is not crucial. This is the easiest method to implement but it can be hard to manage.
  3. Create multiple records with different key values (type 2)
    This provides you with the ability to have an unlimited amount of history.  It is usually implemented by adding a start and end date column.  If you have to make changes to past records this could require you to also update fact records.
  4. Create a new column for previous values (type 3)
    This allows only a fixed amount of history to be retained.  If you create two extra columns for the team attribute you can only store three team values (the current value and last two previous values)

I hope you enjoyed this post.  Next we will cover an introduction to facts and measures.